
Score future or partially observed units under the fitted scoring basis
Source:R/api-prediction.R
predict_mfrm_units.RdScore future or partially observed units under the fitted scoring basis
Usage
predict_mfrm_units(
  fit,
  new_data,
  person = NULL,
  facets = NULL,
  score = NULL,
  weight = NULL,
  person_data = NULL,
  person_id = NULL,
  population_policy = c("error", "omit"),
  interval_level = 0.95,
  scoring_quad_points = 31L,
  readiness_policy = c("error", "review"),
  n_draws = 0,
  seed = NULL,
  adaptive_quad_points = NULL,
  scoring_prior = NULL,
  cut_scores = NULL
)
Arguments
- fit
Output from
fit_mfrm()estimated withmethod = "MML"ormethod = "JML". Whenfituses the latent-regression MML branch (posterior_basis = "population_model"), score the target persons with the same background-variable contract viaperson_data.- new_data
Long-format data for the future or partially observed units to be scored.
- person
Optional person column in
new_data. Defaults to the person column recorded infit.- facets
Optional facet-column mapping for
new_data. Supply either an unnamed character vector in the calibrated facet order or a named vector whose names are the calibrated facet names and whose values are the column names innew_data.- score
Optional score column in
new_data. Defaults to the score column recorded infit.- weight
Optional weight column in
new_data. Defaults to the weight column recorded infit, if any.- person_data
Optional one-row-per-person data.frame with the background variables required by a latent-regression fit. Ignored for ordinary fitted-object posterior scoring. For intercept-only latent-regression fits (
population_formula = ~ 1),mfrmrreconstructs the minimal one-row-per-person table internally from the scored person IDs. This is the scoring-time table fornew_data, not the fit object's replay/export provenance table. For categorical background variables, supply values on the same coding scale used at fit time; the fitted factor levels and contrasts are reused when building the scoring design matrix. Fitted standardization and polynomial/spline bases are also reused; they are not re-estimated from the scoring cohort.- person_id
Optional person-ID column in
person_data. Defaults topersonwhen that column exists, otherwise"Person"for the canonical scoring layout.- population_policy
How missing background data are handled when
fituses the latent-regression branch."error"(default) requires complete person-level covariates for all scored persons;"omit"drops scored persons lacking complete covariates and records that omission inpopulation_review.- interval_level
Posterior interval level returned in
Lower/Upper.- scoring_quad_points
Number of Gauss-Hermite nodes used only for this scoring call. It is independent of the quadrature order used while fitting
fit; the default is 31 and values below 2 are refused. The fixed or adaptive integration mode is inherited fromfit.- readiness_policy
How a source fit that is not scoring-ready is handled.
"error"(default) refuses scoring."review"permits an explicitly review-only fitted-object calculation and labels the returned estimates and settings accordingly; it does not make the source fit ready. GPCM MML and RSM/PCM normal population models may pass the conditional-scoring checks described below even when their global inference audit remains incomplete. GPCM population models with background covariates still require explicit review. Invalid calibration parameters or inconsistent stored prior parameters are refused under either policy. Older population results without the new check records retain their review-only restriction.- n_draws
Optional number of quadrature-grid posterior draws to return per scored person. Use 0 to skip draws.
- seed
Optional seed for reproducible posterior draws.
- adaptive_quad_points
Optional vector of at least two distinct integer orders >= 3, for example
c(31, 61). Addsquadrature_review, comparing a fixed-prior grid with grids centered and scaled to each Person's posterior. Calibration parameters and the prior are held fixed. Inspect both fixed/adaptive differences and movement between adaptive orders; this diagnostic does not replace estimates, intervals or draws. Every scoring call automatically adds reference orders and uses them to check numerical score accuracy, including ordinary RSM/PCM with the retained prior; see below.- scoring_prior
Optional
list(mean = ..., sd = ...)specifying one normal scoring prior shared by all scored persons, on the unchanged calibration ability scale.sdis a standard deviation, not a variance.NULL(default) retains the MML scoring prior; JML uses a post-hoc standard-normal reference prior. Both values must be finite; SD and its representable variance must be positive. Overrides of population models with background covariates are not supported. A supplied prior does not refit the calibration, estimate a new population, or bypass source checks. Numerical scoring checks run under the supplied prior.- cut_scores
Optional finite, strictly increasing ability cuts with optional distinct names. Requires ordinary RSM/PCM and unit weights. A
decisionstable returns continuous probabilities above cuts and within bands (Lower < ability <= Upper), conditional on the point calibration and actual scoring prior. Calibration/population and cut-score estimation uncertainty are excluded. This is not a Person-difference test or a probability of passing a future administration. Cut labels alone do not establish CEFR alignment. Tiny tails have absolute, not relative, numerical accuracy. Useapa_table(x, which = "decisions")or export the saved table.
Value
An object of class mfrm_unit_prediction with components:
estimates: posterior summaries by persondecisions: optional cut-score and ability-band probabilities, with boundaries, labels, priors, availability and uncertainty basisdraws: optional quadrature-grid posterior drawsfit_identity: source calibration, fitted population coding and scoring status used to check reuse with fit-level exportsrow_review: row-level preparation review fornew_datapopulation_review: optional person-level omission review for latent-regression scoringquadrature_review,quadrature_overview: optional unrounded numerical integration comparison and its compact overviewinput_data: cleaned canonical scoring rows retained fromnew_dataperson_data: cleaned or supplied person-level background data used for latent-regression scoring;NULLotherwisesettings: scoring settingsnotes: interpretation notes
Details
predict_mfrm_units() is the individual-unit companion to
predict_mfrm_population(). It uses the fitted calibration and, when
available, the fitted one-dimensional population model to score new or
partially observed persons via Expected A Posteriori (EAP) summaries on a
quadrature grid.
With the default scoring_prior = NULL, when the original fit uses ordinary
method = "MML", the posterior
summaries use that fitted MML calibration and a standard normal scoring
prior, unless a population model was fitted. When the original fit
uses the latent-regression MML branch, the scoring prior is the fitted
conditional normal population model \(\theta \mid x \sim
N(x^\top\hat\beta, \hat\sigma^2)\), so the returned summaries are
population-model-aware posterior EAP estimates. When the original fit uses
method = "JML", mfrmr applies the fitted facet/step parameters with a
standard normal reference prior on the quadrature grid, so the returned
person scores remain fitted-object EAP summaries rather than direct JML
estimates from the fitting step.
When the fitted population model is intercept-only (population_formula = ~ 1), predict_mfrm_units() still uses the fitted population-model basis,
but it can reconstruct the minimal scored-person table internally because no
background covariates are needed beyond the person IDs in new_data.
The current GPCM branch is included in this scoring layer,
so fitted GPCM objects can be used for the same fitted-object
posterior summaries. This does not imply that every downstream diagnostic or
reporting helper has already been generalized to GPCM.
This is appropriate for questions such as:
what posterior location/uncertainty do these partially observed new respondents have under the existing calibration?
how uncertain are those scores, given the observed response pattern?
All non-person facet levels in new_data must already exist in the fitted
calibration. The function does not recalibrate the model, update facet
estimates, or treat overlapping person IDs as the same latent units from the
training data. Person IDs in new_data are treated as labels for the rows
being scored.
When n_draws > 0, the returned draws component contains discrete
quadrature-grid posterior draws that can be used as approximate plausible
values under the fitted scoring basis. They should be interpreted as
posterior uncertainty summaries, not as deterministic future truth values.
For JML fits, this scoring stage is intentionally post hoc: mfrmr uses
the fitted facet and step parameters from the joint-likelihood fit, then
adds a standard normal reference prior by default (or the explicit
scoring_prior) only for the scoring layer so that
new or partially observed units can be summarized on a quadrature grid.
This is a practical fitted-object EAP procedure, not a claim that the
original JML fit itself estimated a population model. It does not reproduce
the training Person joint maximum-likelihood estimates or provide ML/WLE
scoring for new Persons. Posterior uncertainty conditions on the fitted
calibration; it does not include calibration-parameter uncertainty.
Experimental two-family scoring
Two-family GPCM MML supports new Persons with known non-Person facet levels, unit weights and the retained fixed N(0,1) prior. Both slope components, facet locations and the second owner's category steps remain fixed. New combinations of known levels are allowed under the fitted product model; this does not validate those combinations empirically. Repeated Person-facet combinations are rejected. Missing responses are omitted with a warning and row review; Persons without valid responses receive no prior-only score. Unknown levels or scores outside the original category coding are rejected. Prior overrides and person-level population inputs are not supported.
The saved specification, point estimates, objective and convergence must
agree before either readiness policy permits scoring. A finer rule (normally
max(q + 10, 2 * q - 1)) must change the source negative log likelihood per
Person by at most 1e-6 and have maximum absolute gradient per Person at most
1e-6 for conditional source scoring. Source-readiness or refinement failures
require explicit readiness_policy = "review"; invalid calibration records
or failed convergence cannot be enabled by review. No covariance is required.
Each new batch also receives the EAP/SD integration checks described below.
These tolerances are numerical checks, not statistical validity thresholds.
EAP, posterior SD and continuous equal-tail intervals condition on the point
calibration and fixed prior, excluding calibration uncertainty. Numerical
checks do not complete the identification/boundary audits or establish
sampling coverage, population transport or decision accuracy. Settings retain
both owners, component slopes, locations, steps, category coding, observed
calibration combinations and separate source/batch checks through saveRDS()
and summary(). extract_mfrm_calibration() provides the corresponding
portable format 6 route after passing source checks. Use
mfrm_results(fit, scores = scores) to attach matching saved native or
format-6 scores for reports and exports without rescoring. The saved source
identity, calibration and scoring records must agree with the supplied fit;
source/batch checks, omitted rows and review-only labels remain visible.
Conditional scoring and source checks
A finite calibration can define a person's posterior score without proving
that the calibration is the unique global optimum. For one-family GPCM MML and models
with an estimated RSM/PCM normal population, this function checks the
current likelihood, gradient and unregularized joint information using the
same local-solution machinery as compare_mfrm(). Detected identification
deficiencies, inadequate categories and failed convergence do not pass.
RSM/PCM regressions additionally require the consistent full-rank source,
unit weights, direct MML and centered unanchored facets/steps used by
mfrm_population_intervals(). Scoring reuses the fitted predictor coding
and conditional residual variance; no population uncertainty is propagated.
Boundary and identification audits labelled "not evaluated" remain so;
they are not relabelled as completed by these local checks.
Shared-owner GPCM JML can also use conditional scoring with unit weights and no anchors/interactions. Fresh joint objective/gradient and unregularized full-curvature checks must pass; known Person/additive/slope boundary certificates are not overridden by finite optimizer coordinates. Incomplete global identification/boundary audits remain incomplete. Source curvature includes free Person parameters and uses a dense matrix; saved portable calibration avoids repeating it. No MML integration check or formal slope interval is inferred from this JML calculation.
One-family MML calibration checks also compare the retained solution at its fitting order
and a higher order (normally 2 * q - 1, at least q + 10; q + 10 is
used if the larger rule is not representable). They require NLL movement
<= 1e-5, gradient movement <= 1e-4 and a higher-order gradient <= 1e-4,
in addition to the existing local-solution criteria. These are numerical
screening tolerances, not statistical coverage or global-existence guarantees.
For every native scoring route, after a calibration passes, the actual reported EAP and SD are compared
with adaptive reference orders under the same calibration and scoring prior.
The reference includes the scoring order (at least 3 for this comparison)
and a higher order chosen by the same rule. EAP/SD discrepancies and changes
in adaptive EAP, SD and log marginal likelihood must each be <= 1e-5.
Increase scoring_quad_points if this check fails. readiness_policy = "review" retains and labels those scores for inspection instead of stopping.
Nonfinite posterior calculations or invalid parameters cannot be enabled by review.
settings$local_calibration_review records the source checks and
settings$score_integration_review records the per-Person numerical checks.
New outputs set settings$score_integration_required = TRUE; their saved
checks must remain with the scores. Older outputs without these checks can
still be summarized, but are not retrospectively numerically qualified.
SourceScoringReady concerns the calibration; ScoreIntegrationReady
concerns the reported scores. EstimateUse identifies any scores requiring
integration review. These records accompany summaries, draws and exports.
The conditional route has source_scoring_status = "conditional" and does
not change the fit's global InferenceReady or boundary/identification status.
Information-matrix work respects mfrmr.max_information_bytes; unavailable
checks require explicit review, rather than accepting a stale covariance.
For example, a rubric calibration that passes these checks can score new respondents while holding its estimated normal prior fixed. Passing does not establish that the next cohort has the same ability distribution. Calibration and prior estimation uncertainty remain excluded from posterior intervals, and no portable GPCM calibration artifact is created here.
Scoring a later cohort
By default the scoring prior is retained from the fitted model; this function does not
estimate a new cohort's population mean or spread from new_data. For
example, a calibration from an advanced class may not supply a suitable
prior for a beginning class, even when both classes use the same rubric.
With only a few ratings, scores can depend substantially on that prior.
The number of ratings alone is not an information measure: their calibrated
difficulties, discriminations and observed categories also matter.
Inspect extreme response patterns separately; increasing the rating count
does not guarantee less prior sensitivity for every person.
A narrower prior can yield narrower posterior intervals without any new rating evidence. This is greater certainty under a stronger assumption, not evidence that the assessment became more informative. Changing the prior while fixing calibration is a sensitivity analysis; estimating the calibration again changes a different part of the analysis. Neither action alone establishes coverage for a new cohort.
Use scoring_prior = list(mean = 0.5, sd = 1.5), for example, to inspect
another normal-prior assumption while retaining the calibration. Choose
plausible values for your setting; these example numbers are not a default
recommendation. Compare the same response rows under both priors. The
supplied prior is labelled as an analyst assumption, even if its numbers
equal the retained prior. It does not repair a poorly estimated calibration.
PriorMean/PriorSD describe the prior actually used for scoring;
RetainedPriorMean/RetainedPriorSD describe the original scoring prior.
PriorSource distinguishes "retained" from "user_supplied".
RetainedPrior distinguishes an estimated normal population from the
standard normal reference (including post hoc JML scoring). These unrounded
columns accompany estimates, posterior draws and their summaries.
settings$prior_comparison records both priors by person, and
settings$retained_posterior_basis records the original basis. Do not edit
fit$population: its consistency with the retained calibration is checked
independently of scoring_prior. Saving a prediction with saveRDS() stores
a result; it does not create a portable GPCM calibration for future scoring.
Interpreting output
estimatescontains posterior EAP summaries for each person innew_data.LowerandUpperare continuous equal-tail posterior interval bounds at the requestedinterval_level, computed by numerical CDF inversion. EAP, SD, and optional draws still use the selected quadrature rule. These intervals condition on the fitted calibration and scoring prior, including any estimated population coefficients and variance. They exclude uncertainty from estimating calibration or population parameters; they are not confidence intervals at each fixed true Person ability. Their interpretation also depends on the scoring prior: a new population with a different ability mean, spread or shape can have different coverage. More quadrature points check numerical approximation under the same prior; they do not establish that this prior matches the new population.SDis posterior uncertainty under the fitted scoring basis used for scoring.Estimate tables retain
IntervalLevelwithout rounding, the prior form, per-PersonPriorMeanandPriorSD, calibration method, interval method and uncertainty interpretation.WeightedLikelihoodindicates whether any response contribution for that Person was raised to a non-unit weight. Such weights do not by themselves establish equivalent independent ratings or frequentist coverage. Draw tables retain their discrete-grid basis and the same prior and calibration interpretation.draws, when requested, contains approximate plausible values on the fitted quadrature grid.population_review, when present, records whether scored persons were omitted because their background data were incomplete for a latent-regression fit.quadrature_review, when requested, retains unrounded per-Person fixed/adaptive log-marginal, EAP and posterior-SD differences, changes between adaptive orders, and computation status/reasons.summary()also supplies a compactquadrature_overview. Acomputedstatus does not certify accuracy; inspect the differences and any unavailable rows.
Re-summarize older results to recover recorded interval settings and readable notes without changing numerical scores. Prior means/SDs for older estimated-population results may be unavailable because those parameters were not retained in the result. Re-score with the existing fitted model to retain them; no calibration refit is needed. An unrecorded interval algorithm is labelled unavailable, not assumed to use continuous quantiles.
What this does not justify
This helper does not update the original calibration, estimate new non-person facet levels, or produce deterministic future person true values. It scores new response patterns under the fitted calibration and, when applicable, the fitted one-dimensional population model.
References
The posterior summaries follow the usual quadrature-based EAP scoring
framework used in item response modeling under calibrated parameters
(Bock & Mislevy, 1982, pp. 432-433; Bock & Aitkin, 1981).
When fit uses the latent-regression
branch, mfrmr scores under the fitted conditional normal population model
in the general plausible-values spirit discussed by Mislevy (1991). Optional
posterior draws are exposed as quadrature-grid plausible-value-style
summaries for practical many-facet scoring rather than as a claim of full
ConQuest numerical equivalence. When the source fit is JML, the same
literature supports
the quadrature-based scoring layer, but the standard normal prior is a
package-level reference prior introduced for post hoc scoring rather than an
estimated population distribution.
The local JML objective, gradient and curvature cutoffs are package
numerical criteria, not literature-derived guarantees of calibration
accuracy or interval coverage. The scoring literature does not establish
the completeness of the source boundary audit.
Bock, R. D., & Mislevy, R. J. (1982). Adaptive EAP estimation of ability in a microcomputer environment. Applied Psychological Measurement, 6(4), 431-444. doi:10.1177/014662168200600405 .
Bock, R. D., & Aitkin, M. (1981). Marginal maximum likelihood estimation of item parameters: Application of an EM algorithm. Psychometrika, 46(4), 443-459.
Mislevy, R. J. (1991). Randomization-based inference about latent variables from complex samples. Psychometrika, 56(2), 177-196.
Muraki, E. (1992). A generalized partial credit model: Application of an EM algorithm. Applied Psychological Measurement, 16(2), 159-176.
Corrected JML
An experimental shared-owner corrected GPCM calibration can score new
Persons after fresh checks of its adjusted equation, full Jacobian and
saved parameter identities. These checks never apply an unadjusted
likelihood-stationarity requirement to the corrected root. Unit weights
and known facet levels are required; unresolved roots cannot be enabled by
readiness_policy = "review". No model is refitted. The returned EAPs
use the corrected point calibration and a separate normal reference prior,
not the original profiled Person estimates. Continuous posterior intervals
exclude calibration uncertainty and residual calibration bias. The correction
order and estimator remain recorded in the score table and saved settings.
extract_mfrm_calibration() provides the corresponding portable route.
Conditional ability decisions
Supply cut_scores on the calibration's ability scale to obtain
decisions, with one row per Person and requested event. Type = "above_cut"
gives \(P(\theta > c \mid y, \widehat\psi)\); Type = "ability_band"
gives the probability between successive cuts, including the two outer
bands. Lower < ability <= Upper defines every row. Label uses the
supplied cut names (or Cut1, ...) and Band1, ... in increasing order.
These events overlap: only the ability-band probabilities sum to one.
PriorMean and PriorSD record the actual Person-specific normal prior;
Status and Reason retain scoring availability. available_conditional
means the applicable numerical checks passed, not that the model or the
cut's substantive meaning has been validated. review_only requires
inspection before interpretation. Source-roster scoring may return
prior_only for missing-only Persons; portable scoring instead retains
them as unavailable with NA probabilities. Fitted-object scoring omits
Persons with no retained rows; inspect its row and population reviews.
A Person absent from the input is never invented.
Probabilities integrate the continuous posterior, rather than counting
sample_mfrm_plausible_values() draws or applying a normal approximation
to EAP/SD. They condition on point calibration, population/prior parameters
and supplied cuts, as recorded in Uncertainty. They do not propagate
estimation error, compare two Persons or predict passing a future test.
CEFR labels require externally justified cuts on this same scale.
Very small tails have absolute, not relative, numerical accuracy; a
returned zero or one is not a claim of impossibility or certainty.
Review the scoring population as well as the calibration. An estimated normal prior is treated as known during scoring; its sampling uncertainty can matter especially with a small calibration cohort. A larger calibration cohort can improve parameter precision without correcting a prior that mismatches a new population's mean, spread or shape. Passing numerical checks does not establish that probabilities are accurate for that new population. A fixed reference prior is not a universal remedy: justify it for the target population on the calibration scale. If a prior override is supported, comparing externally justified alternatives is a sensitivity analysis, not evidence that the alternative giving the preferred classification is valid. Population-averaged accuracy also does not guarantee accuracy near each cut, within every subgroup or for each individual Person.
Use score_mfrm_persons() for eligible ordinary RSM MML source Persons,
predict_mfrm_units() for ordinary RSM/PCM MML or JML fitted-object scoring, and
score_mfrm_calibration() for eligible continuous-posterior RSM/PCM
artifacts. Each route retains its existing source and population
restrictions. Unit weights are required; GPCM, shared-rater and testlet
cut probabilities are not supported. JML uses a separate scoring prior,
not a population estimated by JML. NULL leaves the existing output unchanged.
summary(x)$decisions and apa_table() with which = "decisions" reuse
saved probabilities without rounding them. Fitted-object and portable
score batches also support build_summary_table_bundle() and
export_summary_appendix(). Save the complete result with saveRDS()
to retain cuts, priors and review states for later reporting. Existing
score plots display EAPs and intervals, not these event probabilities.
Saved-result reuse
Fit-level export and replay helpers check that supplied scores describe the same calibration, fitted population coding and scoring status. Recreate older scores from the saved fit and original scoring inputs/settings; the calibration does not need refitting. See mfrmr_compatibility_layer.
Examples
toy <- load_mfrmr_data("example_core")
keep_people <- unique(toy$Person)[1:18]
toy_fit <- fit_mfrm(
toy[toy$Person %in% keep_people, , drop = FALSE],
"Person", c("Rater", "Criterion"), "Score",
method = "MML",
quad_points = 61
)
raters <- unique(toy$Rater)[1:2]
criteria <- unique(toy$Criterion)[1:2]
new_units <- data.frame(
Person = c("NEW01", "NEW01", "NEW02", "NEW02"),
Rater = c(raters[1], raters[2], raters[1], raters[2]),
Criterion = c(criteria[1], criteria[2], criteria[1], criteria[2]),
Score = c(2, 3, 2, 4)
)
# Illustrative boundaries only: these labels do not establish CEFR levels.
cuts <- c(Basic = -0.5, Advanced = 0.8)
pred_units <- predict_mfrm_units(toy_fit, new_units,
scoring_quad_points = 121, cut_scores = cuts)
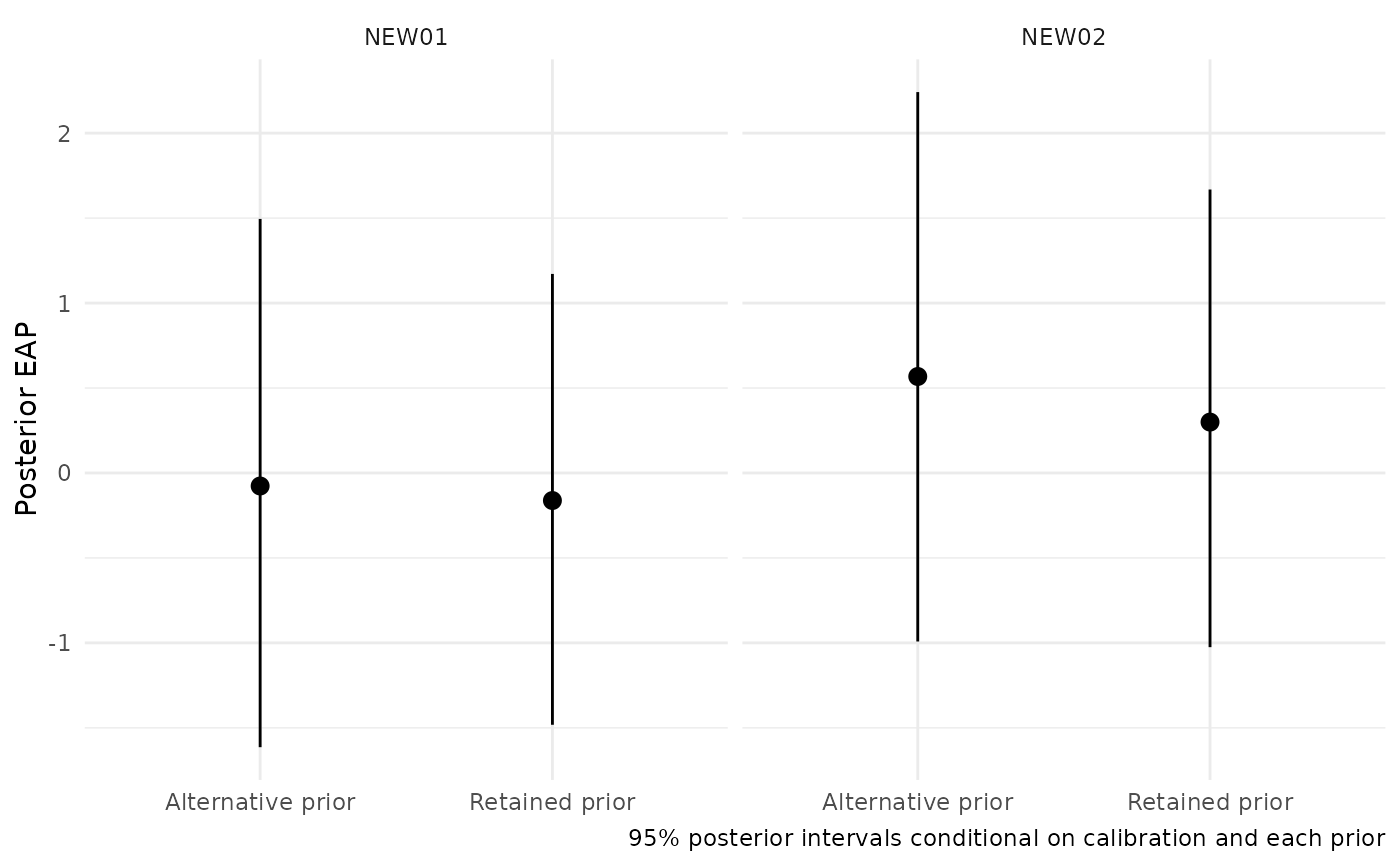
summary(pred_units)$estimates[, c("Person", "Estimate", "Lower", "Upper")]
#> # A tibble: 2 × 4
#> Person Estimate Lower Upper
#> <chr> <dbl> <dbl> <dbl>
#> 1 NEW01 -0.162 -1.48 1.17
#> 2 NEW02 0.3 -1.02 1.67
pred_units$decisions
#> Person Type Label Lower Upper Probability PriorMean PriorSD
#> 1 NEW01 above_cut Basic -0.5 Inf 0.69210796 0 1
#> 2 NEW01 above_cut Advanced 0.8 Inf 0.07706642 0 1
#> 3 NEW01 ability_band Band1 -Inf -0.5 0.30789204 0 1
#> 4 NEW01 ability_band Band2 -0.5 0.8 0.61504154 0 1
#> 5 NEW01 ability_band Band3 0.8 Inf 0.07706642 0 1
#> 6 NEW02 above_cut Basic -0.5 Inf 0.88022925 0 1
#> 7 NEW02 above_cut Advanced 0.8 Inf 0.22964641 0 1
#> 8 NEW02 ability_band Band1 -Inf -0.5 0.11977075 0 1
#> 9 NEW02 ability_band Band2 -0.5 0.8 0.65058285 0 1
#> 10 NEW02 ability_band Band3 0.8 Inf 0.22964641 0 1
#> Status Reason Uncertainty
#> 1 available_conditional conditional_on_point_calibration_and_prior
#> 2 available_conditional conditional_on_point_calibration_and_prior
#> 3 available_conditional conditional_on_point_calibration_and_prior
#> 4 available_conditional conditional_on_point_calibration_and_prior
#> 5 available_conditional conditional_on_point_calibration_and_prior
#> 6 available_conditional conditional_on_point_calibration_and_prior
#> 7 available_conditional conditional_on_point_calibration_and_prior
#> 8 available_conditional conditional_on_point_calibration_and_prior
#> 9 available_conditional conditional_on_point_calibration_and_prior
#> 10 available_conditional conditional_on_point_calibration_and_prior
apa_table(pred_units, which = "decisions")
#> Conditional ability decision probabilities
#> Person Type Label Lower Upper Probability PriorMean PriorSD
#> NEW01 above_cut Basic -0.5 Inf 0.69210796 0 1
#> NEW01 above_cut Advanced 0.8 Inf 0.07706642 0 1
#> NEW01 ability_band Band1 -Inf -0.5 0.30789204 0 1
#> NEW01 ability_band Band2 -0.5 0.8 0.61504154 0 1
#> NEW01 ability_band Band3 0.8 Inf 0.07706642 0 1
#> NEW02 above_cut Basic -0.5 Inf 0.88022925 0 1
#> NEW02 above_cut Advanced 0.8 Inf 0.22964641 0 1
#> NEW02 ability_band Band1 -Inf -0.5 0.11977075 0 1
#> NEW02 ability_band Band2 -0.5 0.8 0.65058285 0 1
#> NEW02 ability_band Band3 0.8 Inf 0.22964641 0 1
#> Status Reason Uncertainty
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> Note. Decision probabilities describe Lower < ability <= Upper on the calibration scale. Calibration, population estimates and supplied cut scores are held fixed. Probability accuracy depends on the scoring prior matching the target population; numerical checks do not validate that match. Uncertainty in an estimated prior is excluded, and a larger calibration sample does not correct a mismatched scoring prior. They are not Person-difference tests or probabilities of passing a future administration. Cut labels do not establish CEFR alignment. Very small tails have absolute, not relative, numerical accuracy.
# Compare assumptions on the same response rows, without refitting.
alternative <- predict_mfrm_units(
toy_fit, new_units, scoring_prior = list(mean = 0.5, sd = 1.5),
scoring_quad_points = 121, cut_scores = cuts
)
comparison <- dplyr::bind_rows(
"Retained prior" = pred_units$estimates,
"Alternative prior" = alternative$estimates, .id = "Scenario"
)
if (requireNamespace("ggplot2", quietly = TRUE)) {
ggplot2::ggplot(comparison, ggplot2::aes(Scenario, Estimate)) +
ggplot2::geom_pointrange(ggplot2::aes(ymin = Lower, ymax = Upper)) +
ggplot2::facet_wrap(~ Person) + ggplot2::theme_minimal() +
ggplot2::labs(x = NULL, y = "Posterior EAP",
caption = "95% posterior intervals conditional on calibration and each prior")
}
 # Retain the complete result; summaries and tables do not score again.
saved <- tempfile(fileext = ".rds")
saveRDS(pred_units, saved)
apa_table(readRDS(saved), which = "decisions")
#> Conditional ability decision probabilities
#> Person Type Label Lower Upper Probability PriorMean PriorSD
#> NEW01 above_cut Basic -0.5 Inf 0.69210796 0 1
#> NEW01 above_cut Advanced 0.8 Inf 0.07706642 0 1
#> NEW01 ability_band Band1 -Inf -0.5 0.30789204 0 1
#> NEW01 ability_band Band2 -0.5 0.8 0.61504154 0 1
#> NEW01 ability_band Band3 0.8 Inf 0.07706642 0 1
#> NEW02 above_cut Basic -0.5 Inf 0.88022925 0 1
#> NEW02 above_cut Advanced 0.8 Inf 0.22964641 0 1
#> NEW02 ability_band Band1 -Inf -0.5 0.11977075 0 1
#> NEW02 ability_band Band2 -0.5 0.8 0.65058285 0 1
#> NEW02 ability_band Band3 0.8 Inf 0.22964641 0 1
#> Status Reason Uncertainty
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> available_conditional conditional_on_point_calibration_and_prior
#> Note. Decision probabilities describe Lower < ability <= Upper on the calibration scale. Calibration, population estimates and supplied cut scores are held fixed. Probability accuracy depends on the scoring prior matching the target population; numerical checks do not validate that match. Uncertainty in an estimated prior is excluded, and a larger calibration sample does not correct a mismatched scoring prior. They are not Person-difference tests or probabilities of passing a future administration. Cut labels do not establish CEFR alignment. Very small tails have absolute, not relative, numerical accuracy.
unlink(saved)